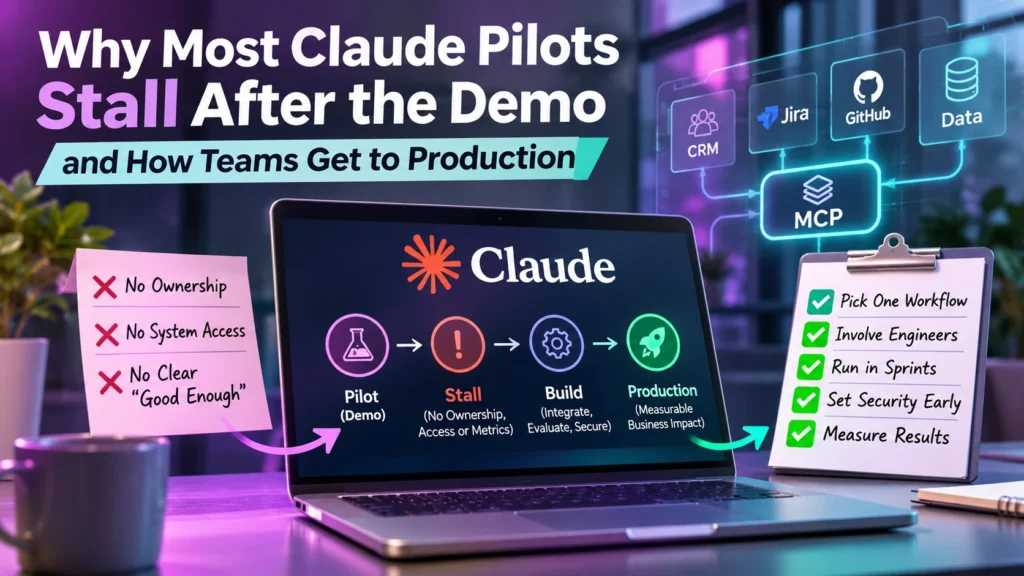
If you only read one paragraph: getting Claude licenses is the easy bit. Pilots die of dull causes. Nobody’s on the hook for a result, Claude can’t get at the systems where the work sits, and nobody ever wrote down what “good enough” means. Sort those out first, then push one workflow all the way into production before anyone starts talking about a company-wide rollout.
You’ve probably sat through this. Somebody drags a 14-tab spreadsheet into Claude in the middle of an all-hands, asks which three accounts look ready to churn, and ten seconds later there’s an answer good enough that a few people clap.
A month on, finance is paying for 300 seats. There’s a #ai-ideas channel in Slack, mostly memes by now. And the support team is still copying text out of Jira into a chat window and back again, by hand, all day.
The model isn’t the bottleneck here. Claude handles code, contracts and ticket triage fine. What nobody budgeted for is the plumbing around it, plus a person whose job it is to make it stick.
Why pilots stall
Nobody owns it
Everyone has access, so no one is accountable. IT approved the purchase. Half a dozen fans use it every day. A manager pastes “212 weekly active users” into the quarterly deck and moves on.
Active users is a nice chart and not much else. Try asking who’s responsible for cutting first-response time in the billing queue, or for moving releases from monthly to weekly. Silence, usually. Name one owner with one number to move and the mood changes fast: access requests stop sitting in a queue, someone makes the unpopular calls, and six weeks later there’s a real answer. Without that, the whole thing just fizzles out by Easter and nobody can say exactly when it died.
Claude can’t reach the work
A chat box sees almost nothing of a business. The actual work is spread across the CRM, the help desk, GitHub, a data warehouse and a shared drive last tidied in 2019. When each task begins with someone exporting a CSV so they can paste it into a prompt, you haven’t saved effort; you’ve relocated it.
MCP (the Model Context Protocol) and tool use in the Claude API exist to fix exactly this. They let Claude reach real systems with proper permissions and a log of what it touched, so it can pull the ticket, see which plan the customer pays for and write the reply inside the help desk itself. None of it is exotic. It’s normal integration work, done by someone who knows your stack and knows how Claude calls tools.
Nobody defined “good enough”
Here’s the usual arc. A team plays with a dozen prompts, likes what comes back and turns it on for a few colleagues. Then a customer asks something odd, gets a wrong answer delivered with total confidence, and someone posts the screenshot in the group chat. That’s the end of trust, roughly by lunchtime.
The cure is unexciting: grab 30 to 50 real cases where you already know the right answer and rerun them whenever the prompt, the model or the data changes. Suddenly “is version two better?” is a question with an answer. Put a cap on spend, add some basic monitoring, and yes, it feels like paperwork in week one. In month two it’s why the feature is still switched on.
What teams that ship do instead
They pick one workflow
Survivors start small. Embarrassingly small, sometimes: one support queue, the Monday pipeline report, a crusty old module nobody volunteers for. You want work that’s frequent, repetitive and already tracked, because then nobody can argue about the baseline afterwards.
Good first candidates look something like these:
- first drafts for a single ticket type, refund requests for example, with a person approving each one;
- tests for a legacy module, written before anybody dares refactor it;
- the weekly CRM export boiled down to half a page the head of sales will actually read;
- a first-pass review of pull requests against the team’s list of repeat mistakes.
None of that makes a keynote. Every bit of it can be measured, which is the point.
They put engineers in the room
Plenty of firms try to close the gap with prompt workshops. Those are fine as far as they go. A workshop won’t build a connector, though, or write an eval set, or ship anything to production.
Software vendors with complicated products figured out a better pattern years ago: the forward deployed engineer. That’s a senior engineer who sits with the customer’s team, works in their repos and tools, and answers for something actually going live. In a Claude rollout, it looks like engineers who spend all day in Claude Code turning up at your stand-ups, wiring Claude into your systems and getting a real pull request merged in the first sprint.
You can hire that person or borrow them for a few months. InterCode, for one, runs Claude activation along these lines: its engineers embed with the client’s product team, ship features, agents and automated workflows on the client’s own stack, then hand over the code, skills and documentation at the end.
They count in sprints
Two weeks works well. Each sprint should finish with something running and a figure next to it, whether that’s tickets drafted, hours saved, tests added or cost per task. If the figure hasn’t moved after two or three sprints, change the workflow or kill it. Killing a weak idea early costs little and frees up budget for a better one.
They settle security on day one
Security reviews sink more pilots than bad answers ever do, so get the boring questions out of the way early. Does Claude run through Anthropic directly, on Amazon Bedrock or on Google Cloud Vertex AI? Which repos and systems is it allowed near? Who reviews connector access, and how often? It helps that Anthropic doesn’t train its models on customer data by default on commercial plans; that tends to answer the security team’s opening question. Your own side still needs an access model, designed on purpose and written down.
A realistic first month
Week one is for choosing the workflow, naming the owner, picking the metric and writing down where it stands today. Week two goes on access, the first connector and those 30 to 50 test cases. In week three a handful of people get a first version, with a human checking every output. Week four is the reckoning: compare against the baseline, fix what the test cases caught, decide whether to widen it.
It won’t look like a transformation program, and that’s fine. One workflow that works tends to win over a leadership team faster than yet another slide deck about AI strategy.
So, what now?
If your rollout has stalled, quit staring at the model and look at ownership, access and evaluation instead. Fix those, choose one thing you can measure, and get it live before adding the next. The companies getting real returns from Claude are rarely the ones with the most seats. They’re the ones who treated it as an engineering project from day one.